ComfyUI runs best on hardware that can sustain GPU load. You want to avoid throttling, surprise restarts, and shared-host “noise.” That’s why many creators deploy ComfyUI on a GPU server instead of treating it like a desktop utility.
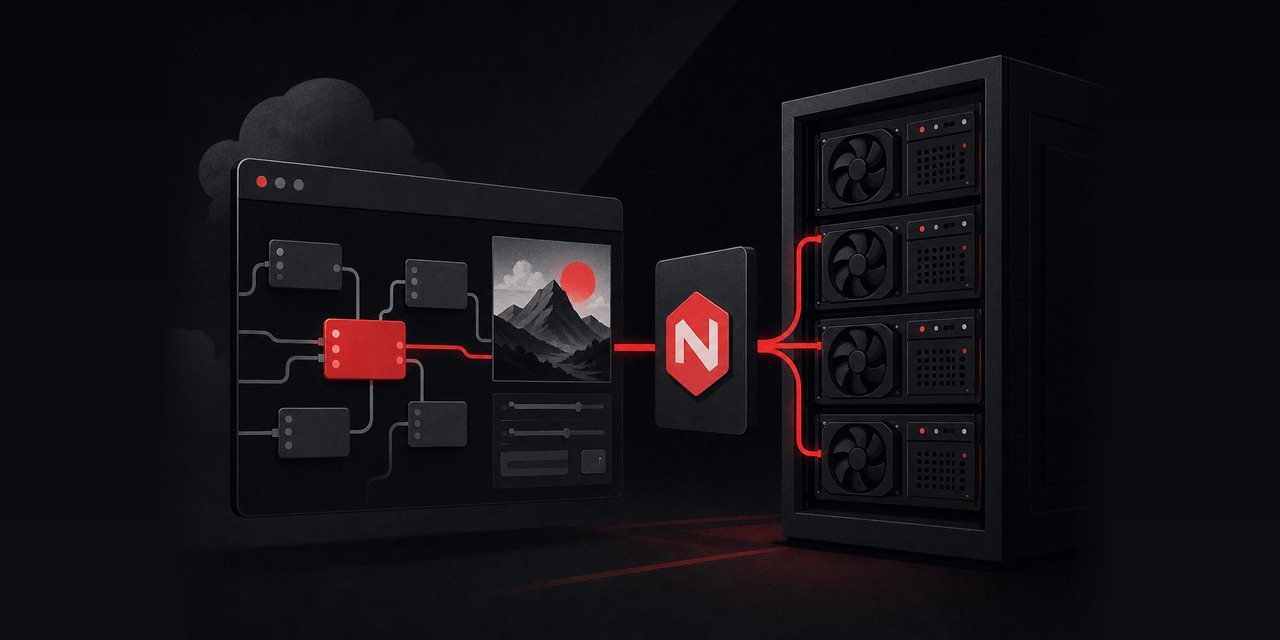
Below, you’ll install ComfyUI on Ubuntu, run it as a systemd service, and publish it behind Nginx. You’ll also add HTTPS and a few sensible guardrails.
This guide assumes you already have a dedicated GPU machine or a GPU-capable VPS. If you’re still picking hardware, a HostMyCode dedicated server is a straightforward way to get consistent GPU performance and enough storage for model files.
What you’ll build (and what you won’t)
- ComfyUI installed into a Python virtual environment under
/opt/comfyui - systemd service so it auto-starts, restarts on failure, and logs cleanly
- Nginx reverse proxy on
https://comfyui.yourdomain.com - TLS certificates via Let’s Encrypt (using Caddy for issuance, then proxying with Nginx)
- Hardening: firewall rules, optional Basic Auth, request limits, and Fail2ban guardrails
This tutorial does not teach prompting or curate a model library. It also won’t promise specific throughput.
Generation speed depends on your GPU, model, resolution, steps, sampler, and how heavy your graph gets.
Prerequisites and sizing: CPU vs GPU vs RAM vs disk
Before you install anything, size the box like a workstation. Don’t size it like a bargain VPS.
The common failure mode is “has a GPU,” but not enough RAM or disk. Then downloads fail and workflows crash mid-run.
- OS: Ubuntu Server LTS on x86_64 (this tutorial uses Ubuntu conventions and paths).
- GPU: NVIDIA CUDA-capable GPU is the smoothest path for most image pipelines. AMD can work, but drivers and PyTorch compatibility often take more effort.
- System RAM: 16 GB works for light use; 32 GB is a safer floor if you run multiple workflows or keep many models around.
- VRAM: 8 GB can handle many SD1.5-style workflows at modest resolutions if you’re careful. 12–16 GB is noticeably easier to live with. High-res passes, heavier models, and stacked control modules want more.
- Disk: Plan for 100–300 GB. Checkpoints, LoRAs, VAEs, ControlNet models, and caches add up quickly.
If you’re on multi-tenant infrastructure, sustained disk I/O matters too. NVMe keeps model loads and caching snappy.
Slow storage can make the UI feel like it freezes during reads and downloads.
Step 1: Point a subdomain to your server
Create a DNS record like comfyui.yourdomain.com pointing to your server’s public IP.
If you manage domains through HostMyCode, set the record in HostMyCode Domains.
If you’re migrating DNS, treat it like any other production change. Lower the TTL ahead of time and avoid last-minute edits.
(Optional) If you want a cleaner cutover process, see Migrate a Domain to Cloudflare DNS Without Downtime.
Step 2: Prepare the server (users, packages, firewall)
SSH into the server using a sudo-capable user.
ssh ubuntu@YOUR_SERVER_IPUpdate packages and install the basics:
sudo apt update
sudo apt -y upgrade
sudo apt -y install git python3 python3-venv python3-pip nginx ufw curl ca-certificates
Create a dedicated service user. This avoids running ComfyUI from your admin account.
It also keeps permissions predictable.
sudo adduser --system --home /opt/comfyui --group comfyuiEnable a minimal firewall: SSH plus HTTP/HTTPS.
sudo ufw allow OpenSSH
sudo ufw allow 80/tcp
sudo ufw allow 443/tcp
sudo ufw enable
sudo ufw status
Step 3: Install NVIDIA drivers and validate the GPU
If your provider image already has working NVIDIA drivers, skip straight to validation.
Otherwise, install drivers using Ubuntu’s recommended server flow.
Install the recommended driver package:
sudo ubuntu-drivers autoinstall
sudo reboot
After reboot, confirm the GPU is visible:
nvidia-smiIf nvidia-smi fails, fix that first. ComfyUI will still install, but it will fall back to CPU.
That’s a time sink because you’ll debug the wrong layer.
Step 4: Install ComfyUI into /opt/comfyui
Clone ComfyUI into the service home. Keeping everything under /opt/comfyui simplifies permissions and backups later.
sudo -u comfyui -H bash -c 'cd /opt/comfyui && git clone https://github.com/comfyanonymous/ComfyUI.git app'Create a virtual environment and install dependencies.
ComfyUI relies on PyTorch, and the correct wheel depends on your CUDA setup. A practical approach is to install the requirements first, then confirm GPU usage in logs.
If you see “CUDA not available,” adjust the torch install afterward.
sudo -u comfyui -H bash -c '
cd /opt/comfyui/app &&
python3 -m venv /opt/comfyui/venv &&
source /opt/comfyui/venv/bin/activate &&
pip install --upgrade pip wheel &&
pip install -r requirements.txt
'
Common pitfall: pip may pull a CPU-only torch build. ComfyUI will start, but it won’t touch your GPU.
You’ll usually spot this once the service is running and you check the journal output. The fix is reinstalling torch with the right CUDA build for your environment.
Step 5: First run (localhost only) to verify ComfyUI starts
Start ComfyUI once on loopback. This confirms dependencies and basic startup before you add Nginx.
sudo -u comfyui -H bash -c '
cd /opt/comfyui/app &&
source /opt/comfyui/venv/bin/activate &&
python main.py --listen 127.0.0.1 --port 8188
'
In another SSH window, verify the port responds locally:
curl -I http://127.0.0.1:8188/Stop the process (Ctrl+C). Next, you’ll run it under systemd.
Step 6: Run ComfyUI with systemd (auto-start, restart, logs)
Create a systemd unit at /etc/systemd/system/comfyui.service:
sudo tee /etc/systemd/system/comfyui.service >/dev/null <<'EOF'
[Unit]
Description=ComfyUI
After=network.target

[Service]
Type=simple
User=comfyui
Group=comfyui
WorkingDirectory=/opt/comfyui/app
Environment=PATH=/opt/comfyui/venv/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin
ExecStart=/opt/comfyui/venv/bin/python /opt/comfyui/app/main.py --listen 127.0.0.1 --port 8188
Restart=on-failure
RestartSec=3

# Hardening (safe defaults)
NoNewPrivileges=true
PrivateTmp=true
ProtectSystem=full
ProtectHome=true
ReadWritePaths=/opt/comfyui

[Install]
WantedBy=multi-user.target
EOF
Reload systemd, enable the service, and start it:
sudo systemctl daemon-reload
sudo systemctl enable --now comfyui
sudo systemctl status comfyui --no-pager
Watch logs during the first launch:
journalctl -u comfyui -fIf it crashes, follow the traceback instead of guessing.
Most first-run failures come down to Python dependencies or file permissions under /opt.
Step 7: Put ComfyUI behind Nginx with HTTPS
Don’t expose ComfyUI directly on port 8188. You want TLS, sane headers, and one place to add auth and rate limits.
Nginx is a clean fit for that job.
First, obtain an HTTPS certificate. If you prefer Caddy’s Let’s Encrypt automation, you can use it for issuance and renewals.
Then keep Nginx as the reverse proxy. HostMyCode walks through that approach here: Set Up Let’s Encrypt With Caddy for a VPS Site.
Once certificates exist on the server, create an Nginx site. This example assumes:
/etc/ssl/comfyui/fullchain.pem/etc/ssl/comfyui/privkey.pem
If your cert files land somewhere else (for example under /var/lib/caddy), update the paths in the Nginx config.
Create /etc/nginx/sites-available/comfyui:
sudo tee /etc/nginx/sites-available/comfyui >/dev/null <<'EOF'
map $http_upgrade $connection_upgrade {
  default upgrade;
  '' close;
}

limit_req_zone $binary_remote_addr zone=comfyui_ratelimit:10m rate=5r/s;

server {
  listen 80;
  server_name comfyui.yourdomain.com;

  location /.well-known/acme-challenge/ {
    root /var/www/html;
  }

  location / {
    return 301 https://$host$request_uri;
  }
}

server {
  listen 443 ssl http2;
  server_name comfyui.yourdomain.com;

  ssl_certificate     /etc/ssl/comfyui/fullchain.pem;
  ssl_certificate_key /etc/ssl/comfyui/privkey.pem;

  # Keep uploads bounded. ComfyUI can upload images and workflows.
  client_max_body_size 50m;

  # Basic abuse control (tune for your use)
  limit_req zone=comfyui_ratelimit burst=20 nodelay;

  add_header X-Frame-Options "SAMEORIGIN" always;
  add_header X-Content-Type-Options "nosniff" always;
  add_header Referrer-Policy "strict-origin-when-cross-origin" always;

  location / {
    proxy_pass http://127.0.0.1:8188;
    proxy_http_version 1.1;

    proxy_set_header Host $host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;

    # WebSocket support (ComfyUI uses it)
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection $connection_upgrade;

    proxy_read_timeout 3600;
    proxy_send_timeout 3600;
  }
}
EOF
Enable the site and reload Nginx:
sudo ln -s /etc/nginx/sites-available/comfyui /etc/nginx/sites-enabled/comfyui
sudo nginx -t
sudo systemctl reload nginx
Open https://comfyui.yourdomain.com. If you hit a 502, use the diagnostics section below.
Step 8: Add authentication (recommended for any Internet-exposed UI)
ComfyUI can trigger expensive GPU work on demand. If you publish it without auth, someone else will eventually find it and spend your compute.
The quickest option is HTTP Basic Auth in Nginx. Install the helper and create a password file:
sudo apt -y install apache2-utils
sudo htpasswd -c /etc/nginx/.htpasswd-comfyui youruser
Then add these two lines inside the location / block in the TLS server:
auth_basic "ComfyUI";
auth_basic_user_file /etc/nginx/.htpasswd-comfyui;
Reload Nginx:
sudo nginx -t && sudo systemctl reload nginxIf you’d rather avoid passwords entirely, a VPN or tunnel is often cleaner.
The operational pattern is the same as internal dashboards: keep it private by default, then expose it intentionally.
Step 9: Model storage layout (keep it tidy)
Messy model storage is how disks fill up quietly. Pick a layout early and stick to it.
Back up what you can’t easily replace. A typical structure under the ComfyUI tree looks like this:
/opt/comfyui/app/models/checkpoints/opt/comfyui/app/models/loras/opt/comfyui/app/models/vae/opt/comfyui/app/models/controlnet(if you use control modules)
Make sure the service user can read the model files:
sudo chown -R comfyui:comfyui /opt/comfyui/app/modelsHonest limitation: once you start experimenting, “small” doesn’t last.
The first few checkpoints may fit in 20–40 GB. After a month of testing, 200 GB is completely normal.
Step 10: Backups that actually restore
You don’t need to back up every cache directory. You do want copies of the pieces you can’t quickly recreate:
- Your workflows and custom nodes (this is your real work product)
- Any fine-tunes, LoRAs, or models you can’t easily re-download
- Your Nginx config and TLS automation config
At minimum, snapshot /opt/comfyui and /etc/nginx.
If you already run backups for other servers, add ComfyUI to the same pipeline. The “restore-first” mindset matters here too.
This HostMyCode guide captures that habit well, even though ComfyUI isn’t a database service: Set Up PostgreSQL Backups With pg_dump + Restore Test.
Quick diagnostics: 502s, broken websockets, and GPU not used
These three problems cover most real-world install issues.
502 Bad Gateway from Nginx
- Check the service state:
sudo systemctl status comfyui --no-pager - Check logs:
journalctl -u comfyui -n 200 --no-pager - Verify the local port responds:
curl -I http://127.0.0.1:8188/
If you want a broader Nginx troubleshooting flow, this HostMyCode guide matches the same failure pattern: Nginx 502 Bad Gateway Fix on Ubuntu VPS.
UI loads, but progress updates don’t stream
This is usually a WebSocket proxy issue. Make sure your Nginx config includes:
proxy_set_header Upgrade $http_upgrade;proxy_set_header Connection $connection_upgrade;
ComfyUI runs, but it’s on CPU
- Confirm the server sees the GPU:
nvidia-smi - Check ComfyUI logs for CUDA detection lines:
journalctl -u comfyui -n 200 --no-pager - In many cases, reinstalling torch with the correct CUDA wheel fixes it (the exact command depends on your CUDA/PyTorch combo).
Don’t ignore this. CPU-only generation on a server tends to feel broken, even if the process technically runs.
Hardening checklist for a public endpoint
If the UI is reachable from the Internet, treat it like an admin panel. Don’t treat it like a toy project.
- Keep ComfyUI bound to localhost (we did:
--listen 127.0.0.1). - Require auth (Basic Auth is the minimum).
- Rate limit at Nginx (we did via
limit_req). Adjust for multi-user use. - Use Fail2ban to slow brute force against your auth prompt. See Set Up Fail2ban for Nginx on Ubuntu VPS.
- Patch monthly:
sudo apt update && sudo apt -y upgrade, then reboot during a maintenance window.
If you host a public website on the same machine, keep your Nginx server blocks tight and your ports minimal.
Mixing “public web” and “private UI” without boundaries is a reliable way to cause avoidable outages.
Operating ComfyUI day to day (start/stop, updates, logs)
These are the commands you’ll reach for most often.
- Restart after config changes:
sudo systemctl restart comfyui - Tail logs:
journalctl -u comfyui -f - Update ComfyUI code (then restart):
sudo -u comfyui -H bash -c 'cd /opt/comfyui/app && git pull'
sudo systemctl restart comfyui
If an update breaks your workflows (it happens), roll back with git log + git checkout <commit>.
Then restart. For production-style setups, boring and stable beats new and fragile.
Where HostMyCode fits (hardware that doesn’t get in your way)
Once you rely on private generation for daily work, uptime and predictability matter more than tinkering.
You want consistent GPU access, enough NVMe for models, and the ability to restrict inbound traffic.
For steady workloads, start on a HostMyCode dedicated server.
If you’d rather spend less time on patching and monitoring, managed VPS hosting can cover the operational basics while you focus on your pipelines and assets.
If you want to deploy ComfyUI on a GPU server and keep it running like a dependable internal tool, start with infrastructure built for sustained load. A HostMyCode dedicated server gives you consistent GPU performance and storage headroom for model growth. If you prefer to offload routine patching and monitoring, use managed VPS hosting for a simpler operations baseline.
FAQ
Should I expose ComfyUI directly to the Internet?
It’s safer not to. If you must, put it behind HTTPS, require authentication, and add rate limits.
Binding ComfyUI to 127.0.0.1 and proxying through Nginx is the right starting point.
How much VRAM do I need for ComfyUI?
8 GB can work for lighter workflows, but you’ll make compromises on resolution and modules.
12–16 GB is a more comfortable baseline for regular use, especially if you stack conditioning, control modules, or high-res passes.
Why do I get an Nginx 502 error?
Usually because ComfyUI isn’t running, crashed on startup, or is listening on a different IP/port.
Check systemctl status comfyui and then journalctl -u comfyui. Also confirm curl http://127.0.0.1:8188 works locally.
Can I run ComfyUI on a CPU-only VPS?
You can, but it will feel unusably slow for most image pipelines. If you need private generation for real work, plan on a GPU server.
How do I keep the server from filling up?
Put models on a dedicated disk path and periodically prune what you don’t use.
Track disk usage with df -h and du -sh /opt/comfyui/app/models/*. Model collections grow faster than most people expect.